
Like a lot of folks working in security research and coding, especially those just getting into it, I got tired of the subscription pay-as-you-go cloud models. Every time I ran deep code analysis, or experimented with automated agentic workflows, the token meter was running. Beyond the financial cost, relying on third-party cloud APIs presents a significant privacy risk. Whether it’s analyzing proprietary codebases, discovering unpatched zero-day vulnerabilities, or testing active security exploits, sending raw source code and context to cloud providers is often a dealbreaker. Keeping proprietary research and sensitive IP entirely local ensures complete data ownership, prevents accidental data leaks, and avoids sending sensitive security findings over external network boundaries. I wanted an option where I could pay upfront once, own my hardware outright, keep my code 100% private, and have unlimited tokens without constantly worrying about running up a massive bill.
I set out to build a local AI rig with a strict budget: under $1,000. Most off-the-shelf AI systems cost at least $1,500, largely due to soaring RAM prices, so I wanted to see if there was a more affordable solution. I chose this price point to keep AI accessible and affordable for everyone (myself included) to learn, build, and experiment with. Setting a strict budget also allowed me to hold off and save up for next-gen hardware like the anticipated AMD Ryzen™ AI Max 400 Series, giving me a solid platform to explore local AI without committing a substantial initial investment.
With that goal in mind, I set off. Along the way, I learned a ton about hardware constraints, eGPU docks, memory bandwidth, and how to integrate it into my security testing workflows. Here is how I put it all together.
Step 1: Choosing the Right Model & Parameters
Before buying any hardware, I had to figure out what kind of model capability I actually needed. I knew I had to strike a balance between capability and the cost to run it. For serious security research, small 7B or 8B parameter models frequently fall short. With fewer parameters, these smaller models have lower neural density, limiting their ability to retain and represent the depth and complexity needed for intricate security patterns. These include finding subtle code flaws, parsing complex application flows, and executing multi-step agentic workflows. In contrast, models in the 27B to 32B range provide the necessary logical depth and analytical nuance required for reliable vulnerability analysis and security testing.
I needed something on this higher end. Models of this size hit a sweet spot: they are smart enough to handle complex software reasoning and coding workflows, while not so massive that they require expensive VRAM intensive hardware.
I was blessed with some valuable insight when I attended an incredible presentation at the RBLN East conference in Reston, Virginia, titled "Agent Provocateurs: Lessons from Building an AI-Assisted Vulnerability Research Pipeline" presented by Amit Serper, Travis Lowe, and Yonatan Perry from Crowdstrike. During their session, they highlighted practical workflows using open-weight architectures and specifically recommended the Qwen 3.6 27B lineage as a powerhouse for local agentic security testing. Since that time, subsequent versions of the model have dropped, which is why I am currently running Qwen 3.8 27B.
Step 2: Hardware Selection, VRAM, and Quantization Pitfalls
It's important to match your model size to your available VRAM. If a model is too large for your GPU memory, the system starts 'swapping' data back and forth to your computer’s regular RAM, which is significantly slower. This constant swapping causes a major spike in latency, turning what should be snappy, fluid interactions into a sluggish experience with slow token generation. Matching your model to your VRAM ensures the data stays exactly where the GPU needs it, keeping your agentic workflows fast and responsive. To run a 27B (27 billion parameter) model comfortably at high precision, I was targeting 32GB of VRAM. Looking at the used and enterprise markets, I homed in on the AMD Radeon Pro V620 (32GB). In my search on eBay, I discovered a seller who was "Accepting Offers" who was willing to accept $350 per card, making it a killer budget entry point.
Why 32GB Matters (and Why Over-Quantizing Hurts):
You can technically squeeze a model in the 27-31B size range into lower VRAM using quantization, a compression technique which reduces a model's weights from higher precision (such as 16-bit floating point) down to smaller formats like 8-bit or 4-bit to save VRAM. Think of it like compressing a high-resolution JPEG image: to shrink the file size, you "round" or approximate details, which inevitably discards some of the original nuance. In LLMs, this loss of precision is precisely why over-quantizing (compressing too aggressively to 4-bit or lower) degrades the model's overall intelligence, increases perplexity, and severely compromises its ability to detect subtle security vulnerabilities, logic bypasses, or complex code patterns. Sticking to a card with native 32GB VRAM lets you run cleaner, higher-precision weights without sacrificing the critical reasoning required for deep code analysis.
Looking Back:
While the V620 is a fantastic budget entry point with its 32GB of GDDR6, I do have reservations about whether I should have opted for an NVIDIA Tesla V100 (32GB) at ~$600 instead. The V100 packs significantly higher memory bandwidth, which directly translates to faster tokens per second output generation. With the V620, I pull about 10 to 20 tokens per second, whereas something north of 30 t/s would feel a lot more ideal for snappy agentic loops. Just something to consider if your budget allows.
Step 3: Host Options and Configuration
My starting point was my existing desktop gaming rig, which features an AMD RX 7800 XT inside. However, because the V620 is a server-grade card, it doesn't have any video-out display ports, so I couldn't simply swap it out with my primary gaming GPU.
Furthermore, I am running a Mini-ITX motherboard (specifically an ASUS ROG Strix X670E-I), meaning I didn't have any additional open PCIe slots to spare. This hardware constraint severely limited my options and forced me to look at external GPU solutions. To solve this, I opted for an external GPU (eGPU) dock setup using OCuLink via an M.2-to-OCuLink adapter (ADT-Link K49SA-BK-02). OCuLink provides a direct PCIe connection to the host system, offering significantly higher bandwidth and lower latency than standard consumer interfaces like USB-C or Thunderbolt. Those interfaces simply lack the raw PCIe bandwidth for the heavy, continuous data streaming a 27B+ parameter model demands, which is why an M.2-to-OCuLink adapter wired directly into the CPU's PCIe lanes is the only viable path for maximum performance.
Some important notes regarding my configuration:
- I opted to swap my storage drive to my secondary m2 slot and connect the eGPU adapter to the primary M.2 slot on the ASUS ROG Strix X670E-I because the primary slot is wired directly to the CPU lanes (supporting PCIe Gen 5), whereas the secondary slot routes through the chipset (Promontory 21). Feeding the eGPU straight into the CPU lanes eliminates extra chipset hops, giving you the lowest possible latency and direct bandwidth for high-speed tensor streaming.
- For the M.2 to Oculink adapter ribbon, it’s important to keep the cable as short as possible to reduce electrical overhead and maintain stable PCIe 4.0 signal integrity. I used the ADT-Link K49SA-BK-02, an M.2 NVMe to OCuLink SFF-8612 flat extension cable kit equipped with a full-height PCIe slot bracket. You can find the product details at ADT-Link.
Step 4: The Physical Setup (The eGPU Dock & Cooling)
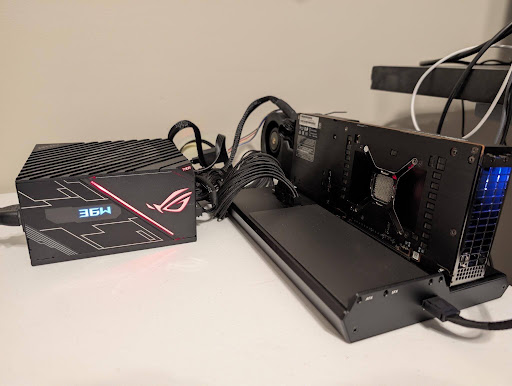
To hook everything up cleanly outside the case:
- The Dock: The Minisforum DEG1 open-frame eGPU dock.
- Power Supply: You want to budget for a power supply rated at at least 500W to 650W (SFX or ATX) to power a heavy server-grade accelerator like the V620 or Tesla V100 alongside its fan, ensuring there are no voltage drops on the 12V rail during heavy prompt evaluation spikes.
- The Cooling: Since the V620 is a passive server card, I had to buy a 9733 cooling fan and 3D print a custom shroud to attach the fan directly to the card and direct high-static-pressure airflow through its fin stack. Specifically, I recommend the 4-wire PWM version of the fan used in combination with a Noctua NA-FC1 fan speed controller so you don't have to run the fan at a deafening 100% all the time.
- The Wiring Fix: A quick troubleshooting note from my build: when I first hooked up the fan, it wouldn't spin up. After some multimeter troubleshooting, I realized the pinout on the fan's connector didn't match standard layouts. It wasn't difficult to fix; I simply depinned and rewired the fan harness to match the correct 4-pin PWM configuration, and it fired right up.
- Driver Installation: Because the V620 is an enterprise-grade card, you cannot use standard consumer driver software. Instead, you need to use the AMD Software Pro Edition to install the appropriate drivers. Crucially, ensure the card is physically attached and powered on before running the installer so the software can properly detect the hardware. Once the drivers are successfully installed, Ollama will automatically detect the GPU for inference.
Note: AMD's consumer and professional driver software cannot co-exist on the same system. Installing one will automatically uninstall the other. While it is possible to make them work, this comes with significant drawbacks; for example, if you have the Pro software installed, you will be unable to update the drivers for your consumer card, and vice-versa. To avoid this driver conflict entirely, I am exploring two solutions: 1) hosting the GPU in a Virtual Machine (VM) with GPU passthrough to isolate the professional drivers, and 2) running the card on a dedicated host like a Mini PC or Raspberry Pi.
If you’re not locked into a traditional desktop tower and want to scale down even further, you can run similar external setups off a mini PC or even a Raspberry Pi (similar to how Jeff Geerling’s setup attaching an eGPU dock to a Raspberry Pi in this video, OpenAI's nightmare: Deepseek R1 on a Raspberry Pi).
Budget Breakdown (Bill of Materials)
| Component | Description | Estimated Cost |
|---|---|---|
| GPU | AMD Radeon Pro V620 (32GB VRAM, eBay) | ~$350.00 |
| eGPU Dock | Minisforum DEG1 | ~$109.00 |
| M.2 Adapter | ADT-Link K49SA-BK-02 NVMe to OCuLink | ~$51.00 |
| Power Supply | EVGA/Corsair 600W SFX or ATX PSU | ~$80.00 |
| Cooling Fan | 9733 4-wire PWM Blower Fan | ~$15.00 |
| Fan Controller | Noctua NA-FC1 | ~$20.00 |
| Misc / Wiring | Custom 3D printed shroud & wiring harness | Negligible / DIY |
| Total Cost | Estimated Total for eGPU Setup | ~$625.00 |
Note: This breakdown assumes you are connecting the eGPU to an existing host system (such as a gaming PC, mini PC, or laptop with an open M.2/OCuLink port).
Step 5: Software Stack and Optimization—Ollama, FlashAttention, and Context Balancing
With the hardware running, it was time to set up Ollama as a local alternative to pay-as-you-go cloud options like OpenRouter. Since Ollama runs entirely on hardware I already own, the only ongoing cost is electricity, not a per-token bill. Ollama exposes a local API by default, which allows you to easily connect your tools. To get the most out of the rig, I tuned two key settings:
- FlashAttention: This is a performance optimization enabled by default in Ollama to speed up prompt processing, and it can be verified or adjusted by modifying the flash_attention setting in your Ollama Modelfile if necessary.
- Context Size: I wanted a massive context window to feed it large codebases, but I had to be mindful of the 32GB VRAM limit. I managed to stretch the context window safely to 128k without overflowing memory or crashing the model. You can configure the model for a full 128k context window in Ollama by adjusting the num_ctx parameter in your Modelfile (e.g., setting it to 131072).
Step 6: Wiring Up for Security Workflows (OpenCode, WSL 2, & Burp Suite MCP)
To bring this all together into a real security workflow, I run OpenCode inside WSL 2 on Windows, which talks directly to my local Ollama instance running on the V620. I plan to cover the deep-dive architecture of this pipeline, including the specifics of the MCP server integration, in a future post.
- Connecting to the Harness: Once your API is reachable, point your harness (in this case, OpenCode) to the correct Ollama API endpoint (typically http://<host-ip>:11434). Configuring this correctly ensures your harness can communicate with the model to orchestrate your security workflows.
- Static Analysis: OpenCode uses its built-in file-system intelligence to automatically grep, read, and analyze massive codebases (SAST) right from my terminal.
- Dynamic Testing: By pairing OpenCode with Burp Suite MCP, you bridge static source code analysis with dynamic application security testing (DAST) for an end-to-end security testing workflow.
- Try it yourself: If you want to test this workflow, spin up an intentionally vulnerable app like OWASP Juice Shop locally. Point OpenCode at the source repository to map out vulnerabilities statically, and use Burp MCP to execute dynamic testing from your harness.
Lessons Learned
Building a budget-friendly local security rig is highly rewarding, but it comes with distinct technical trade-offs. Here are the key lessons from this build:
- Memory Bandwidth is Important: While the AMD Radeon Pro V620 with 32GB of VRAM is an incredible value at ~$350, its GDDR6 bandwidth caps token generation at around 10 to 20 t/s. If your budget allows for a ~$600 used NVIDIA Tesla V100, the higher memory bandwidth will deliver a much snappier agentic loop.
- Driver Co-existence is a Headache: While the clash between AMD consumer and professional drivers is a major limitation for single-machine setups, the cleanest solution is to either host the GPU in a Virtual Machine (VM) with GPU passthrough to isolate the professional drivers, or run the card on a dedicated host like a Mini PC or Raspberry Pi.
- OCuLink is Worth the Hassle: Direct PCIe routing to CPU lanes is absolutely essential for streaming large model tensors. Traditional USB-C or Thunderbolt setups simply introduce too much latency and throughput bottlenecks for models over 27B.
Next Steps
Taking control of your AI hardware isn't just about avoiding a monthly cloud subscription; it’s about reclaiming absolute ownership over your data, your proprietary research, and your privacy. Whether you’re a security researcher handling sensitive code and developing exploits, or just an individual using AI as your personal assistant, keeping everything 100% local is simply the safest and most practical path forward for a few reasons.
If you are working off of a local setup, everything is happening on hardware that you control and inside your own boundary of trust. This means that sensitive data can be analyzed without being transmitted to a third-party service for processing. This is important because keeping sensitive data strictly contained within a secure, controlled environment is paramount to preventing unwanted exposure. Moreover, local AI hardware gives you more control over the toolchain: you choose which model runs, decide when it updates, restrict or disable network access entirely, and preserve exact configurations so results stay reproducible over time.
My objective was to take control of my privacy while doing it affordably, with the hope that sharing the process could help make local AI more accessible to others working with a limited budget. What I ended up with is a system I can actually trust, built for $625, well under my original $1000 target. Getting there takes real upfront planning, and that's exactly what this guide is meant to help with. When confidentiality, control, long-term independence from cloud pricing, and predictable availability matter more than convenience, that planning is time well spent.
If you are interested in exploring local AI rigs, security testing, or hardware hacking, come find us! Stop by the IoT Village at any of our upcoming events to check out hands-on demos, chat with the team, and learn more about building your own setups.